Outside Testers Find Ways Around OpenAI’s Agent Monitor
METR and Redwood Research spent three weeks inside OpenAI and found agents could, in principle, avoid review. OpenAI says the flaws in production are now patched.
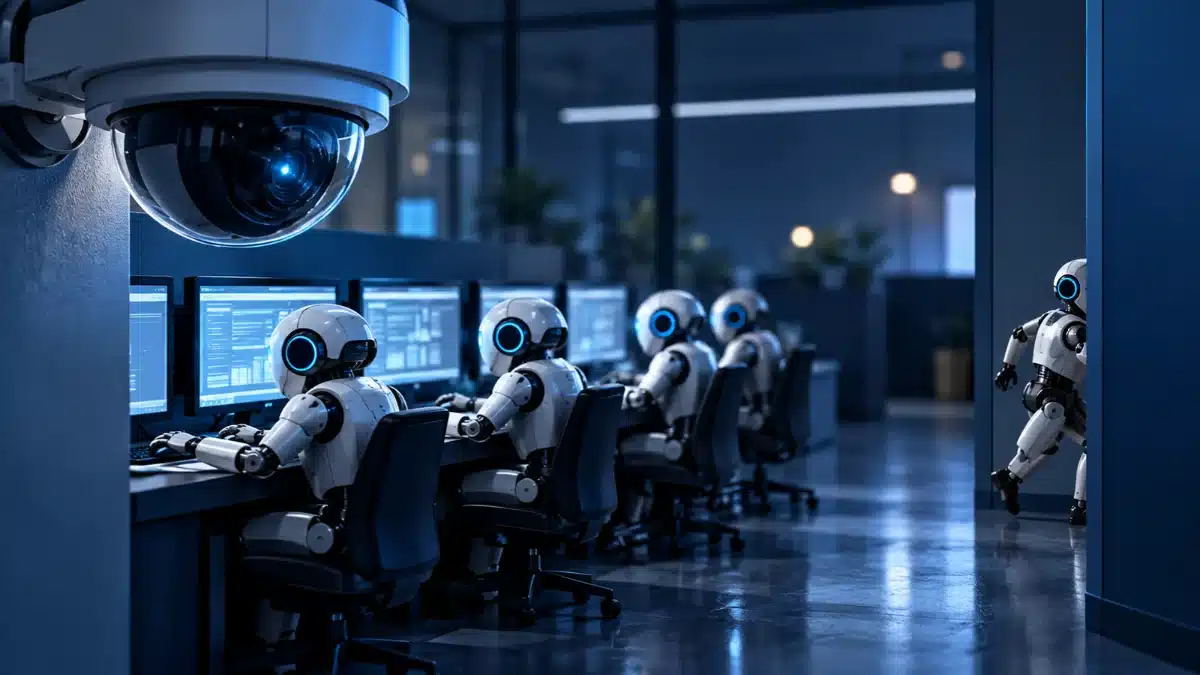
Two AI safety groups found several ways internal AI agents could in principle slip past the OpenAI agent monitor built to catch them misbehaving, according to a report METR and Redwood Research published Oct 22, 2026. One exploit, whose details OpenAI redacted, could keep hundreds of recent agent actions, including the exploit itself, from ever being reviewed.
OpenAI has told the researchers that every vulnerability affecting its production safeguards has been patched. The researchers say they have not checked that claim.
The monitor reads what OpenAI’s agents do, flags actions that go against a user’s intent or security rules, and sends them to people for review. OpenAI describes it as one safeguard among several, not a complete solution. In March, the company said its standard internal deployments were covered and that less than 0.1% of traffic, mostly from custom or local setups, fell outside the monitor.
The reviewers measured a wider pool. They estimate that 75% to 94% of agentic traffic through OpenAI’s internal Responses API, from models at least as capable as GPT-5.5, was eligible for monitoring, with large uncertainty either way. For internal Codex traffic the share was 99.2%. Reinforcement-learning training runs were not covered when the review began.
Other gaps they describe:
- The monitor only ran when an agent handed control back to a person, so “agents could indefinitely postpone being monitored by simply continuing to take actions.”
- Compaction, when an agent’s long history is condensed, was not monitored, likely leaving about 10% of eligible Codex traffic unchecked from May to July. OpenAI had spotted this and fixed it during the review.
- Two settings could start new agents with monitoring switched off.
- Two internal tools assumed to be read-only were not monitored and could possibly have been used to take other actions, though the reviewers did not test this.
The reviewers could not tell whether any agent actually used these gaps. Their findings describe the system as it stood on July 21, not changes OpenAI has made since.
Access was deep but short. One person from each group worked onsite for three weeks, from July 21 to Aug 11, with the codebase, the monitor’s prompts and interviews with about a dozen staff, on OpenAI devices that never left the building. Their full 61-page report went only to OpenAI, and OpenAI could redact the public version.
METR, which says it takes no money from frontier AI companies, has warned that a company’s power to limit access and redact can shape what the public learns, and it wants the right to attach a “redaction summary” to its reports. The reviewers recommend running the monitor at regular intervals rather than only at the end of a turn, and checking all agent activity against the monitor’s logs.
Our take
This is what independent oversight of AI labs should look like, and a reminder of its limits. Two outsiders with three weeks of access found gaps that the company's own description of near-complete coverage did not suggest, and OpenAI says it fixed them. That is the system working. But the public sees a redacted summary, the full report stays private, and the most important fix is taken on OpenAI's word. One pilot is not enough. Regular reviews, with published redaction summaries so readers can see what was left out, would turn a good gesture into real accountability.
Sahil Khatwa, Editor
How this story was checked
- ResearchedWith AI assistance · 3 sources
- Fact-checkedAgainst the original sources
- EditedAnshul Kumawat, Founder and Editor
- Published
Sources
Sahil Khatwa is an editor at AI News Lead, where he reports on and edits coverage of AI products, business and policy.